When an AI agent does something wrong, the first questions are what it did, with what data, and who approved it. These five patterns log the answers. They follow the current OpenTelemetry GenAI semantic conventions and keep prompt content out of your telemetry unless you decide otherwise.
Part of the TypeScript AI Agent Security series. This is the logging and audit trail deep-dive. Start with the complete TypeScript AI agent security playbook, or see the companion guides on authorization patterns and output validation.
| Pattern | What it logs | Why you'd want it |
|---|---|---|
| 1. OpenTelemetry inference spans | Provider, model, token usage, latency, errors; content only on opt-in | Debugging and cost; the base layer for everything else |
| 2. Redaction before capture | Prompts with emails, phone numbers, SSNs and card numbers masked | Keeps personal data out of observability backends |
| 3. Append-only audit record | Who, when, which agent, input hash, outcome | Incident review; EU AI Act logs for high-risk systems |
| 4. Session token tracker | Tokens and cost per session and user | Budget limits and cost attribution |
| 5. Human review trail | Agent draft, confidence, reviewer decision, override reason | Evidence that a person checked the output |
TL;DR: Use the GenAI conventions for spans (Pattern 1) with content capture off, redact before you turn it on (Pattern 2), and write decisions and reviews to append-only tables (Patterns 3 and 5). Track tokens per session (Pattern 4) so a runaway loop shows up as a number.
What changed in the OpenTelemetry GenAI conventions
Three changes matter if you wrote GenAI instrumentation from an older tutorial, including an earlier version of this post.
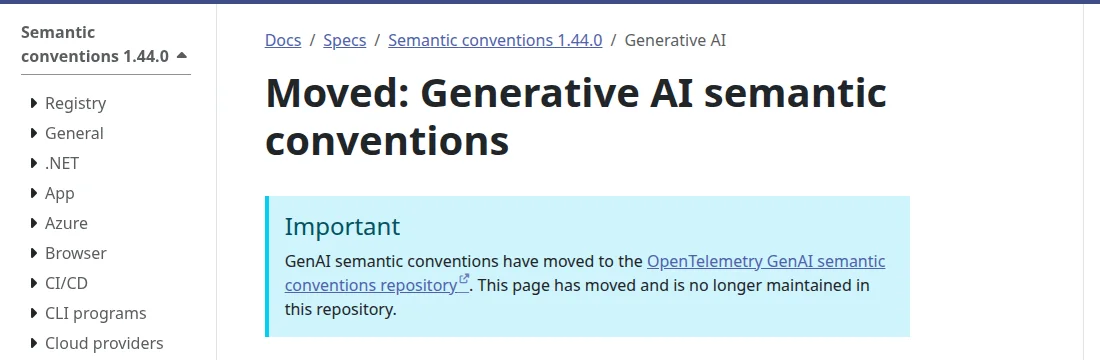
Screenshot: opentelemetry.io, Semantic conventions 1.44.0, Generative AI page. Captured October 31, 2026.
- The GenAI conventions moved out of the main semantic conventions docs into a separate OpenTelemetry GenAI semantic conventions repository. They're still marked Development, so names can change.
gen_ai.systemis deprecated and replaced bygen_ai.provider.name. The oldgen_ai.promptandgen_ai.completionattributes were removed with no replacement; content now goes ingen_ai.input.messages,gen_ai.output.messagesandgen_ai.system_instructions.- Instrumentations "SHOULD NOT capture" instructions, inputs and outputs by default. If a library supports capture through an environment variable, it must be
OTEL_INSTRUMENTATION_GENAI_CAPTURE_CONTENT, and the default value isNO_CONTENT.
For production, the spec recommends storing content externally and recording references on the span, because external storage "enables separate access controls."
Pattern 1: OpenTelemetry inference spans
Name the span {operation} {model}, set the provider and model, record token usage from the response, and only attach content when capture is switched on.
import { trace, SpanKind, SpanStatusCode } from "@opentelemetry/api";

const tracer = trace.getTracer("ai-agent", "1.0.0");

// Same variable name and values the GenAI conventions define for instrumentations.
type CaptureMode = "NO_CONTENT" | "SPAN_ONLY" | "EVENT_ONLY" | "SPAN_AND_EVENT";
const captureMode = (process.env.OTEL_INSTRUMENTATION_GENAI_CAPTURE_CONTENT ?? "NO_CONTENT")
  .toUpperCase() as CaptureMode;
const captureOnSpans = captureMode === "SPAN_ONLY" || captureMode === "SPAN_AND_EVENT";

interface ChatMessage { role: string; content: string }

interface LLMCallParams {
  provider: string;          // e.g. "openai", "anthropic"
  model: string;
  messages: ChatMessage[];
  maxTokens?: number;
  sessionId: string;
}

interface LLMResult {
  content: string;
  model: string;             // model name returned by the provider
  usage: { inputTokens: number; outputTokens: number };
}

// Messages in the conventions' parts format, serialized to a JSON string on spans.
const toInputMessages = (messages: ChatMessage[]) =>
  JSON.stringify(messages.map((m) => ({ role: m.role, parts: [{ type: "text", content: m.content }] })));

export async function tracedLLMCall(
  params: LLMCallParams,
  llmFn: () => Promise<LLMResult>,
  redact: (text: string) => string = (t) => t, // plug in Pattern 2
): Promise<LLMResult> {
  return tracer.startActiveSpan(
    `chat ${params.model}`,
    { kind: SpanKind.CLIENT },
    async (span) => {
      span.setAttributes({
        "gen_ai.operation.name": "chat",
        "gen_ai.provider.name": params.provider,
        "gen_ai.request.model": params.model,
        "session.id": params.sessionId,
      });
      if (params.maxTokens) span.setAttribute("gen_ai.request.max_tokens", params.maxTokens);

      if (captureOnSpans) {
        span.setAttribute(
          "gen_ai.input.messages",
          toInputMessages(params.messages.map((m) => ({ ...m, content: redact(m.content) }))),
        );
      }

      try {
        const result = await llmFn();
        span.setAttributes({
          "gen_ai.response.model": result.model,
          "gen_ai.usage.input_tokens": result.usage.inputTokens,
          "gen_ai.usage.output_tokens": result.usage.outputTokens,
        });
        if (captureOnSpans) {
          span.setAttribute(
            "gen_ai.output.messages",
            toInputMessages([{ role: "assistant", content: redact(result.content) }]),
          );
        }
        return result;
      } catch (err) {
        span.setAttribute("error.type", err instanceof Error ? err.name : "_OTHER");
        span.setStatus({ code: SpanStatusCode.ERROR, message: String(err) });
        span.recordException(err as Error);
        throw err;
      } finally {
        span.end();
      }
    },
  );
}
The user ID is left off the span on purpose. Put it in the audit record (Pattern 3), which you control, rather than in every trace your vendor stores.
Pattern 2: Redact before capture
If you do turn on content capture, mask obvious identifiers before the text reaches the span. Post-processing in the collector works too, but then the raw text has already left your process.
type RedactionRule = { pattern: RegExp; label: string };

const PII_RULES: RedactionRule[] = [
  { pattern: /\b[A-Z0-9._%+-]+@[A-Z0-9.-]+\.[A-Z]{2,}\b/gi, label: "EMAIL" },
  { pattern: /\b\d{3}-\d{2}-\d{4}\b/g, label: "SSN" },
  { pattern: /\b\d{4}[\s-]?\d{4}[\s-]?\d{4}[\s-]?\d{4}\b/g, label: "CARD" },
  { pattern: /\b\d{3}[-.\s]?\d{3}[-.\s]?\d{4}\b/g, label: "PHONE" },
];

export function redactForTrace(text: string): string {
  let safe = text;
  for (const rule of PII_RULES) safe = safe.replace(rule.pattern, `[${rule.label}]`);
  return safe;
}

// Usage with Pattern 1:
// await tracedLLMCall(params, () => client.chat(params), redactForTrace);
Regexes catch structured identifiers only. Names and addresses need an entity-recognition model, and even then some personal data gets through. If prompts that contain personal data reach an observability vendor, that vendor is processing it for you, and GDPR Article 28(3) requires a contract with it.
Pattern 3: Append-only audit record
One row per agent action, written once and never updated. This is the log you'd hand to an incident reviewer or, for a high-risk system under the EU AI Act, keep for the retention period.
import { createHash, randomUUID } from "node:crypto";

interface AuditRecord {
  id: string;
  timestamp: string;          // ISO 8601 UTC
  sessionId: string;
  userId: string;
  agentId: string;
  operationType: "inference" | "tool_call" | "decision" | "escalation";
  model: string;
  inputHash: string;          // SHA-256 of the input, not the input
  outputSummary: string;      // a summary you chose to keep, not raw output
  confidence?: number;
  humanReviewRequired: boolean;
  policyViolation?: string;
  durationMs: number;
  tokenUsage: { input: number; output: number };
}

export const sha256 = (text: string) => createHash("sha256").update(text).digest("hex");

interface AuditStore {
  insert(record: AuditRecord): Promise<void>;                 // INSERT only; no UPDATE or DELETE grants
  range(from: Date, to: Date): Promise<AuditRecord[]>;
}

export class AuditLogger {
  constructor(private store: AuditStore) {}

  async log(record: Omit<AuditRecord, "id" | "timestamp">): Promise<string> {
    const entry: AuditRecord = { ...record, id: randomUUID(), timestamp: new Date().toISOString() };
    await this.store.insert(entry);
    return entry.id;
  }

  exportRange(from: Date, to: Date) {
    return this.store.range(from, to);
  }
}
Enforce "append-only" in the database, not just in code: give the application role INSERT and SELECT on the audit table and nothing else. Storing a hash instead of the input keeps personal data out of the table; if you need the original for an investigation, keep it in a separate encrypted store with its own retention rule.
On the EU AI Act: Article 12 requires high-risk systems to "technically allow for the automatic recording of events (logs) over the lifetime of the system." Providers keep those logs under Article 19 and deployers under Article 26(6), in both cases for at least six months unless other law says otherwise. For Annex III systems, those obligations apply from December 2, 2027.
Image: Pexels, used under the Pexels License.
Pattern 4: Session token tracker
Count tokens and cost per session so a looping agent hits a limit. Load prices from config; they change, and hardcoded per-token prices in code go stale. Feed the result into the cost circuit breaker from the output validation patterns.
type Pricing = Record<string, { inputPerMTok: number; outputPerMTok: number }>; // USD per million tokens

interface SessionTotals { userId: string; inputTokens: number; outputTokens: number; costUsd: number }

export class SessionTokenTracker {
  private sessions = new Map<string, SessionTotals>();

  constructor(private pricing: Pricing, private maxCostUsd: number) {}

  record(sessionId: string, userId: string, model: string, inputTokens: number, outputTokens: number) {
    const price = this.pricing[model];
    if (!price) throw new Error(`No price configured for model ${model}`); // don't silently count $0

    const s = this.sessions.get(sessionId) ?? { userId, inputTokens: 0, outputTokens: 0, costUsd: 0 };
    s.inputTokens += inputTokens;
    s.outputTokens += outputTokens;
    s.costUsd += (inputTokens * price.inputPerMTok + outputTokens * price.outputPerMTok) / 1_000_000;
    this.sessions.set(sessionId, s);

    if (s.costUsd > this.maxCostUsd) {
      throw new Error(`Session ${sessionId} over budget: $${s.costUsd.toFixed(4)}`);
    }
    return s;
  }
}

// const tracker = new SessionTokenTracker(loadPricingFromConfig(), Number(process.env.SESSION_MAX_USD));
The CISA token guidance post covers what else to log per request so a spike is easy to trace.
Pattern 5: Human review trail
Record the agent's draft, then each human decision as a new event. Never overwrite the draft: the point of the trail is to show what the agent proposed and what a person changed.
import { randomUUID } from "node:crypto";

type ReviewOutcome = "automated" | "escalated" | "confirmed" | "overridden";

interface DecisionEvent {
  decisionId: string;
  at: string;
  outcome: ReviewOutcome;
  reviewerRef?: string;       // opaque ID you can map to a person internally
  humanDecision?: string;
  reason?: string;
}

interface DecisionDraft {
  decisionId: string;
  sessionId: string;
  queryHash: string;
  agentDraft: string;
  agentConfidence: number;
  agentRationale: string;
}

export class DecisionTrail {
  private drafts = new Map<string, DecisionDraft>();
  private events: DecisionEvent[] = [];           // replace with an append-only table

  constructor(private autoApproveAt = 0.8) {}

  record(draft: Omit<DecisionDraft, "decisionId">): string {
    const decisionId = randomUUID();
    this.drafts.set(decisionId, { ...draft, decisionId });
    this.events.push({
      decisionId,
      at: new Date().toISOString(),
      outcome: draft.agentConfidence >= this.autoApproveAt ? "automated" : "escalated",
    });
    return decisionId;
  }

  review(decisionId: string, reviewerRef: string, outcome: "confirmed" | "overridden", humanDecision?: string, reason?: string) {
    if (!this.drafts.has(decisionId)) throw new Error(`Decision ${decisionId} not found`);
    this.events.push({ decisionId, at: new Date().toISOString(), outcome, reviewerRef, humanDecision, reason });
  }

  history(decisionId: string) {
    return { draft: this.drafts.get(decisionId), events: this.events.filter((e) => e.decisionId === decisionId) };
  }
}
The reviewerRef field follows a point raised in the OpenTelemetry GenAI repository's discussion of tool-approval telemetry. AgentGymLeader cautioned against requiring a raw approver identity, because "These spans can leave the originating system, so an opaque actor reference (or role / decision actor id) is safer than an approver_id that carries PII." In the same thread, Rul1an drew the line this pattern keeps: "telemetry observes the approval decision. It does not become the approval authority."
A log of reviews doesn't by itself meet the AI Act's oversight rule. Article 26(2) asks deployers to "assign human oversight to natural persons who have the necessary competence, training and authority"; this trail is how you show those people actually reviewed the output.
Wiring it together
const audit = new AuditLogger(auditStore);
const tokens = new SessionTokenTracker(pricing, maxSessionUsd);
const trail = new DecisionTrail();

export async function instrumentedAgentCall(sessionId: string, userId: string, query: string) {
  const started = Date.now();
  const params = { provider: "openai", model: "gpt-4o", messages: [{ role: "user", content: query }], sessionId };

  // Patterns 1 and 2
  const result = await tracedLLMCall(params, () => llmClient.chat(params), redactForTrace);

  // Pattern 4
  tokens.record(sessionId, userId, result.model, result.usage.inputTokens, result.usage.outputTokens);

  // Pattern 5
  const decisionId = trail.record({
    sessionId,
    queryHash: sha256(query),
    agentDraft: result.content,
    agentConfidence: scoreConfidence(result),   // from your validation layer
    agentRationale: "structured output passed schema validation",
  });

  // Pattern 3
  await audit.log({
    sessionId, userId,
    agentId: "main-agent",
    operationType: "decision",
    model: result.model,
    inputHash: sha256(query),
    outputSummary: `decision ${decisionId}`,
    humanReviewRequired: trail.history(decisionId).events[0].outcome === "escalated",
    durationMs: Date.now() - started,
    tokenUsage: { input: result.usage.inputTokens, output: result.usage.outputTokens },
  });

  return result.content;
}
Liudmila Molkova of Grafana Labs walks through recording GenAI conversation data with OpenTelemetry and separating the sensitive parts in this KubeCon talk:
Our take
The mistake we'd most want to avoid is sending full prompts to a tracing vendor while keeping no audit table of your own. The GenAI conventions now push the right way: content off by default, opt-in when you need it, and external storage for production. Build Patterns 1 and 3 first. Add content capture only after redaction is in place and your observability vendor is under a processor contract, and keep human review as appended events so nobody can quietly rewrite what the agent proposed.
Correction (October 31, 2026): Earlier versions used the deprecated gen_ai.system attribute and the removed gen_ai.prompt and gen_ai.completion fields, logged prompts and completions by default, and cited semantic conventions v1.37 and v1.38; the GenAI conventions are now maintained in a separate repository, use gen_ai.provider.name, and capture no content by default. The post also said span attributes are "retained forever," linked EU AI Act logging to an August 2, 2026 enforcement date (Annex III high-risk rules apply from December 2, 2027), said a review log "satisfies" the Act's human oversight requirements, and cited SOC 2 CC6 and an "EEOC automated decision audit trail" without a source. Those claims were corrected or removed, and Pattern 5 no longer overwrites the original draft.
Related reading
- CISA AI token guidance: a denial-of-wallet playbook, what to log per request so a token spike shows up
- TypeScript AI agent output validation patterns, validate before logging; Pattern 6 (cost circuit breaker) pairs with token tracking above
- TypeScript AI agent authorization patterns, what the agent is allowed to call; logging proves it stayed within bounds
- EU AI Act compliance checklist, including the logging duties for high-risk systems
- TypeScript AI agent observability and tracing patterns, distributed tracing for production agents, the next layer above structured logging
References
- OpenTelemetry, GenAI semantic conventions repository
- OpenTelemetry, GenAI spans: capturing instructions, inputs and outputs
- OpenTelemetry, Deprecated GenAI attributes registry
- EU AI Act, consolidated text as of July 27, 2026, Articles 12, 19, 26