
A June 23, 2025 summary judgment order in Bartz et al. v. Anthropic was one of the first US rulings on AI training data copyright: training on the books was fair use, scanning purchased print books was fair use, and the pirated copies downloaded to build a central library were not. The case then settled for $1.5 billion.
At a glance: Judge William Alsup found training on the books fair use but the pirated library copies not, and the $1.5 billion settlement got final approval on July 20, 2026. For small teams, data provenance is now a vendor question, ask vendors what data their models were trained on.
The distinction sounds simple. The governance implications are not. For small teams deploying AI tools built on other companies' models, the AI training data copyright governance question is no longer theoretical, it is a supply chain risk that belongs in your vendor due diligence process.
Key Takeaways
- One district court (N.D. Cal., June 2025) drew a practical line: training on the books was fair use, keeping pirated copies in a central library was not. It is not binding on other courts.
- The how of data acquisition is now a legal risk factor for every AI model in your stack. Vendors that used third-party scraping services with piracy exposure carry liability risk that may flow downstream to deployers.
- As a deployer, your exposure is reduced (not eliminated) by contractual indemnification from your AI vendor and documented due diligence showing you asked the right questions.
- The In Re OpenAI Copyright Litigation MDL has produced court orders requiring production of AI output logs, establishing that output traceability is becoming a legal evidentiary standard.
- Data provenance governance, knowing where training data came from and how it was acquired, is now a standard risk control, not a nice-to-have.

Image: Unsplash.
Summary
The Bartz settlement puts $1.5 billion on the table for the owners of the 482,460 books on the Works List. The fair use question was answered earlier, in Judge Alsup's June 2025 order: training on the books was fair use, but the pirated copies Anthropic downloaded to build its library were not, so how the copies were obtained and kept still matters, separately from the training itself. The order describes Anthropic downloading books from Books3, Library Genesis (LibGen) and the Pirate Library Mirror (PiLiMi), over seven million pirated copies in all. For governance practitioners, the immediate implication is that vendor due diligence must now include a data provenance question.
What the Bartz Ruling Actually Decided
| Question | Ruling | What it means for teams |
|---|---|---|
| Was training the models on the books fair use? | Yes: summary judgment for Anthropic that "the training use was a fair use" (June 23, 2025) | Training models on books has one district court ruling on its side, though the same order found the pirated library copies not fair use |
| Were pirated copies (Books3, LibGen, PiLiMi) kept in a central library fair use? | No, "not justified by a fair use"; set for trial, then settled | Vendors whose training sets include piracy-sourced data remain exposed |
| How much do authors receive in the settlement? | About $3,000 per work, less costs and fees; 440,490 of 482,460 works claimed (91.3%) by April 16, 2026; $1.5 billion fund | Sets a floor for future licensing negotiations; signals that copyright holders will pursue claims |
| Does the fair use ruling protect downstream deployers? | Partially, direct training liability falls on model providers; 3 downstream risks remain | Vendor indemnification gaps, fine-tuning with unlicensed data, and output traceability for discovery |
| Is output traceability (what the model produced) also at risk? | Yes, OpenAI MDL courts ordered production of millions of AI output logs | Systems without audit trails face discovery sanctions risk in litigation |
Bartz et al. v. Anthropic was a class action brought by authors whose books Anthropic downloaded from the pirate datasets LibGen and PiLiMi. Judge Araceli Martínez-Olguín heard the final approval motion on May 14, 2026 (an April 8 order moved the hearing to that date) and granted final approval on July 20, 2026. The court puts the payment at about $3,000 per work, less costs and fees. By April 16, 2026, claims covered 440,490 of the 482,460 works, a 91.3% rate. The settlement website expects to send the first payments on or before November 15, 2026.
Judge William Alsup's June 23, 2025 order on fair use, before the settlement:
Training the models on the books = fair use. The court applied the four-factor fair use analysis and found that using copyrighted books to train an AI model is transformative, the model learns patterns and relationships rather than reproducing the original expression. This is the principle AI companies have argued since the first training data lawsuits. The court accepted it, at least for Anthropic's training methodology, as a question separate from how the library copies were obtained.
Pirated library copies = no fair use. Anthropic also downloaded millions of books from pirate sites to build a central library it meant to keep "forever". The order held that these copies "were not justified by a fair use", refused to treat them as training copies, and set them for trial with the resulting damages. How the data was acquired, not only how it was used, decided this part.
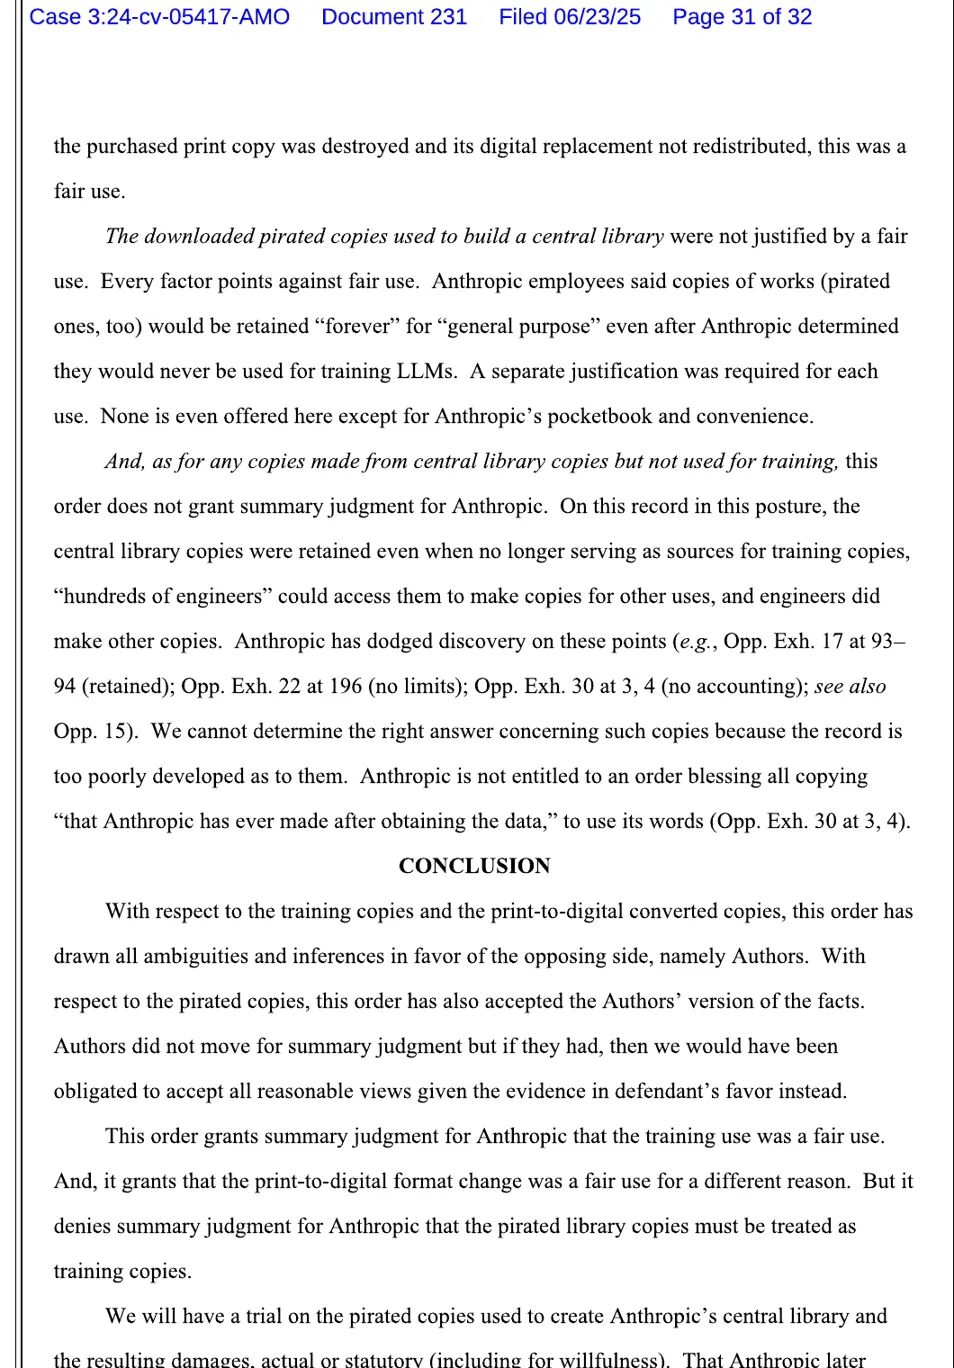
Screenshot: Order on Fair Use, Bartz v. Anthropic, No. 3:24-cv-05417, Dkt. 231, page 31, from the court-approved settlement website. Captured November 4, 2026.
Authors receive compensation. The settlement does not mean authors had no valid claim, it means the case settled before trial on the pirated copies. The monetary outcome (about $3,000 per work before costs and fees, final approval July 20, 2026) represents a floor that will shape future licensing negotiations across the industry.
The Parallel OpenAI Litigation
In In Re OpenAI Copyright Litigation, a consolidated MDL involving dozens of publisher and author plaintiffs, courts have issued discovery orders requiring OpenAI to produce millions of AI output logs through March 2026. The significance for governance practitioners: courts are treating AI outputs as evidentiary artifacts that must be preserved and produced. Systems that cannot produce a meaningful audit trail of what was generated and from what context face discovery sanctions risk.
This is a different governance implication than the training data question. Training data governance is about upstream risk (what was the model trained on). Output traceability is about downstream risk (what did the model produce, when, and to whom). Both are now in the legal spotlight.
Why This Matters for Small Teams
Most small teams did not train the AI models they use. They deploy foundation models built by Anthropic, OpenAI, Google, Mistral, or other providers. The direct training data copyright risk falls on the model providers, but three downstream risks reach deployers:
Vendor indemnification gaps. If your vendor trained on pirated data and faces a successful copyright infringement claim, your vendor's liability exposure may affect their ability to continue providing the service, may result in model takedowns, and may create contractual claims against deployers in certain scenarios. Most off-the-shelf AI vendor agreements do not include explicit indemnification for training data copyright claims. After Bartz, this gap is worth closing.
Fine-tuning with unlicensed data. Many teams fine-tune foundation models on their own data. If that fine-tuning data includes unlicensed copyrighted content, marketing copy scraped from competitor sites, product documentation reproduced without license, academic papers pulled from piracy databases, the fine-tuned model may carry infringement exposure that the foundation model fair use ruling does not cover.
Output copyright and traceability. The OpenAI MDL discovery orders establish that AI outputs may need to be preserved and produced. Reviewing the TypeScript AI agent security playbook for how to build evidence preservation into your stack is a useful starting point. If your organization uses AI to generate content at scale and cannot produce a log of what was generated and when, you face evidentiary risk in any copyright dispute over that content. The audit logger pattern in the playbook handles exactly this requirement, logging outputs, not just inputs.
Governance Goals
For a small team, the training data copyright ruling translates into three concrete governance additions:
- Vendor data provenance documentation: obtain and retain written confirmation from each AI vendor about the lawful basis for their training data acquisition. This does not need to be exhaustive, a written statement that the vendor's training data was lawfully acquired, with any known exceptions disclosed, is a reasonable standard.
- Fine-tuning data inventory: for any model your team fine-tunes or trains internally, maintain a documented record of all training data sources and how each was acquired. Flag any sources that relied on scraping without explicit permission.
- Output logging: ensure that AI-generated content your organization publishes or acts on is logged with timestamp, model version, and prompt context. This is both a governance control and a legal preservation requirement.
Controls: What to Actually Do
This week:
- Review your primary AI vendor contracts. Look for any training data indemnification clause. Note if one is absent, this is a gap to close at renewal or in a contract amendment.
- Identify any internal AI fine-tuning projects. Ask the team where the fine-tuning data came from and whether it was acquired with the right to use for training.
This month:
- Add a training data provenance question to your AI vendor due diligence checklist: "Please confirm the training data used for this model was lawfully acquired. Disclose any known exceptions or pending copyright litigation related to training data."
- For any fine-tuning data that includes scraped web content, legal documents, or published works, get a legal opinion on whether the acquisition method supports the intended use.
- Implement output logging for any AI-generated content published externally or used in consequential decisions.
Ongoing:
- Monitor the In Re OpenAI Copyright Litigation MDL for further discovery rulings. The precedents being set on output log preservation standards will become de facto requirements for any organization using foundation models commercially.
- Review AI vendor agreements at each renewal for training data indemnification language. This will become standard in enterprise AI contracts over the next 12-18 months.
Checklist (Copy/Paste)
- Review AI vendor contracts for training data indemnification coverage
- Document gaps, identify vendors with no training data warranty or indemnification
- Add training data provenance question to vendor due diligence process
- Inventory all internal fine-tuning and training data sources
- Flag any fine-tuning data acquired through scraping or piracy-adjacent channels
- Obtain legal opinion on any ambiguous fine-tuning data sources
- Implement output logging for AI-generated content published externally
- Retain AI output logs consistent with litigation hold policy (minimum 3 years recommended)
Implementation Steps
- Day 1: Pull current AI vendor contracts. Search for "training data," "indemnification," and "copyright." Note whether any training data warranty exists.
- Week 1: Contact your top 3-5 AI vendors and request a written statement on the lawful basis for their training data. Reputable vendors will have a standard response.
- Week 2: Audit internal fine-tuning projects. For each, document the data sources and how they were acquired.
- Week 3: Confirm output logging is in place for AI-generated content used in consequential decisions or published externally. If not, implement it.
- Month 2: Add training data provenance to the standard vendor onboarding and renewal checklist. Make it a routine question, not an ad hoc one.
- Ongoing: Track the OpenAI MDL and similar output-tracing cases for emerging standards on what "adequate AI output logs" means legally.
Frequently Asked Questions
Q: Our AI vendor says they cannot disclose specifics about their training data for competitive reasons. What should we do? A: Request at minimum a written warranty that the training data was lawfully acquired, without requiring disclosure of the specific sources. This is a standard contractual representation that does not expose competitive information. If a vendor refuses to provide even this, escalate to legal, the refusal itself is a risk signal.
Q: We use open-source models. Does this ruling apply to us? A: Yes. The fair use / piracy distinction applies regardless of whether the model is proprietary or open-source. Several widely used open-source training datasets (including versions of Common Crawl derivatives and the Books corpora) have known piracy exposure. Check whether the specific model version you use has a documented training data card and whether that card discloses the acquisition method.
Q: If Anthropic's training was ruled fair use, doesn't that settle the question for all AI training? A: No. The fair use ruling is one district court's order on Anthropic's own record, and the case then settled, so no appeals court reviewed it. It is persuasive, not binding law. Other cases involving different training methodologies, different data sources, or different jurisdictions may reach different conclusions. The ruling reduces uncertainty but does not eliminate the legal landscape.
Q: What does "output logging" actually require in practice? A: At minimum: a record of what was generated (the output), when it was generated, by which model version, and in what context (the prompt or request). For high-risk outputs, those used in consequential decisions or published at scale, also log who reviewed the output before use. This matches the emerging standard from the OpenAI discovery orders.
Updated June 2026: The White House national AI legislative framework (March 2026) says the Administration believes training AI models on copyrighted material does not violate copyright law, but leaves the question to the courts. For non-US operations, the EU's text and data mining exception under the CDSM Directive continues to be the clearest opt-out path for EU-based rights holders.
Correction (November 4, 2026): Earlier versions said a 2026 settlement confirmed that training on licensed works is fair use, that the court made fair use conditional on lawfully acquired data, that final approval was granted at the May 14, 2026 hearing, that authors get $3,100 per work and that payments began in June 2026. The fair use ruling is Judge William Alsup's June 23, 2025 order (Order on Fair Use, Dkt. 231): training was fair use, and the pirated library copies were a separate question that went to trial. Final approval came on July 20, 2026 (Dkt. 680), the court puts the award at about $3,000 per work less costs and fees, and the settlement website expects the first payments on or before November 15, 2026.
References
- Bartz et al. v. Anthropic, settlement analysis (AI Business): https://aibusiness.com/generative-ai/ai-lawsuits-in-2026-settlements-licensing-deals-litigation
- AI in Litigation: Update on AI Copyright Cases in 2026 (Norton Rose Fulbright): https://www.nortonrosefulbright.com/en/knowledge/publications/ce8eaa5f/ai-in-litigation-series-an-update-on-ai-copyright-cases-in-2026
- NIST AI Risk Management Framework, Govern and Map functions: https://nvlpubs.nist.gov/nistpubs/ai/NIST.AI.100-1.pdf
- EU Copyright in the Digital Single Market Directive, TDM exception (EUR-Lex): https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=CELEX%3A32019L0790
- The White House, National Policy Framework for Artificial Intelligence: Legislative Recommendations (March 20, 2026): https://www.whitehouse.gov/wp-content/uploads/2026/03/03.20.26-National-Policy-Framework-for-Artificial-Intelligence-Legislative-Recommendations.pdf
- Bartz v. Anthropic, Order on Fair Use (Dkt. 231, June 23, 2025) and Order Granting Final Approval (Dkt. 680, July 20, 2026), via the court-approved settlement website: https://www.anthropiccopyrightsettlement.com/documents